How to Choose an AI Model for Customer Support in 2026
A practical routing framework for customer-support AI: triage, grounded answers, tool actions, escalation, evaluation and cost per resolved case.
Summary
The wrong way to design AI customer support is to ask one question:
Which model should answer all of our tickets?
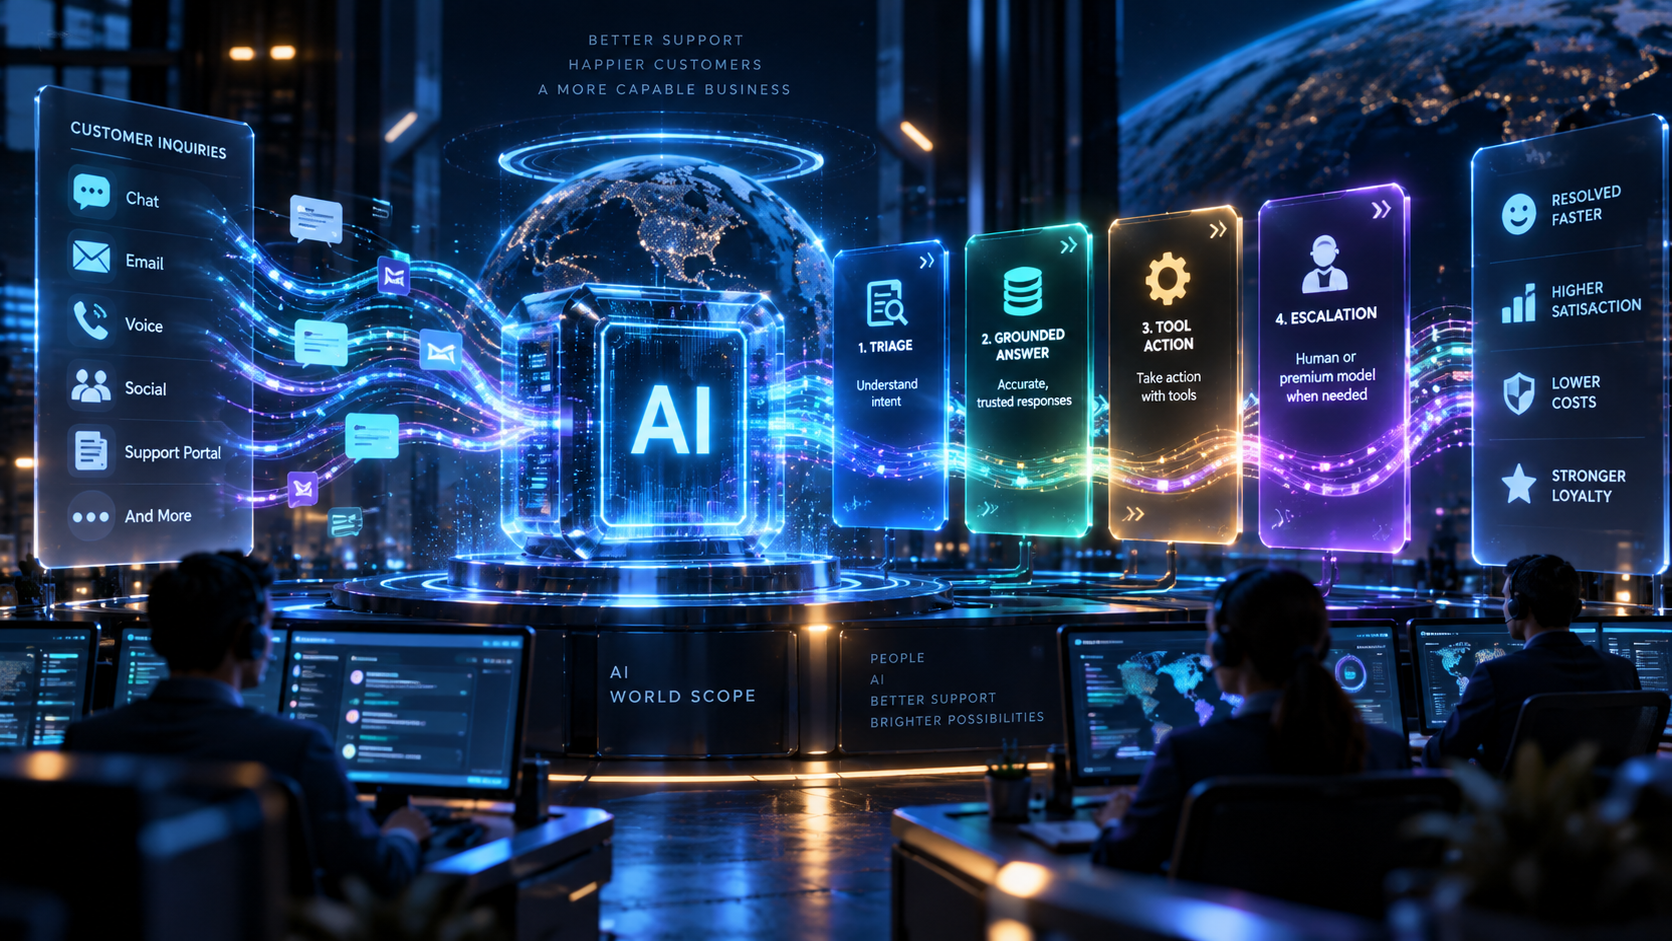
Customer-support workloads are a mix of very different tasks. A system may need to classify intent, detect urgency, extract an order number, retrieve the right policy, compose a response, call a CRM tool, issue a refund, summarize a long customer history and decide when a human should take over.
One model rarely optimizes all of those jobs at once.
A stronger 2026 architecture uses routing:
- a low-cost model for triage and structured extraction,
- a grounded response layer for normal conversations,
- tightly controlled tools for account-changing actions,
- a stronger model or human agent for difficult and risky cases.
This guide focuses on that system design. It does not claim that one model is universally best for support, and it does not repeat our separate AI Customer Support Cost: 1,000 to 100,000 Conversations analysis.
Quick Take
- Do not route every request to a premium frontier model.
- Gemini 2.5 Flash-Lite is explicitly positioned by Google for high-volume classification and simple extraction.
- GPT-5.6 Luna is an inexpensive 1.05M-context model for cost-sensitive high-volume workloads.
- Claude Sonnet 5 is positioned by Anthropic for customer-facing agents and offers a higher-capability escalation path at $2/$10 per million input/output tokens.
- Mistral Small 4 adds an Apache 2.0 open-weight option for teams that care about customization or deployment control.
- Measure cost per resolved case, not cost per model call.
Start with the support workflow, not the model leaderboard
A support conversation typically moves through four different stages.
Stage 1: Triage
The system needs to identify things such as:
- intent,
- language,
- product or account,
- urgency,
- sentiment or complaint type,
- whether structured data can be extracted,
- whether the ticket belongs to a specialized queue.
This stage should usually be optimized for speed, consistency and cost.
Google describes Gemini 2.5 Flash-Lite as its most cost-efficient multimodal model and specifically recommends it for high-volume classification, simple data extraction and extremely low-latency applications.
That makes it an obvious model to evaluate for first-pass routing.
GPT-5.6 Luna is another candidate. OpenAI describes it as optimized for cost-sensitive, high-volume workloads, with a current price of $0.20 input and $1.20 output per million tokens.
Neither description proves that the model will classify your ticket taxonomy correctly. It tells you that the provider designed the model for the economic shape of this layer.
Your evaluation still needs your own intents, languages and edge cases.
Stage 2: Produce a grounded answer
Once the system understands the request, the next problem is not "write a good sentence."
It is:
find the right evidence and answer without violating policy.
A reliable support response may need:
- knowledge-base retrieval,
- policy documents,
- product documentation,
- order history,
- account state,
- previous messages,
- region-specific terms,
- current promotions or service status.
This is where retrieval architecture often matters more than adding another reasoning level.
The model should be tested on:
- whether it uses the supplied policy rather than inventing one,
- whether it cites or points to the right source when required,
- whether it notices contradictory or outdated documents,
- whether it asks for missing information,
- whether it keeps customer-specific data separated correctly.
For routine grounded replies, a lower-cost model may be sufficient.
For long conversation history or large attached documents, context capacity becomes more relevant. GPT-5.6 Luna provides a 1.05M-token context window, while Gemini 2.5 Flash-Lite lists 1,048,576 input tokens. Large context does not remove the need for retrieval, but it creates more architectural headroom.
Stage 3: Take an action through tools
Support becomes much more valuable — and much more dangerous — when the AI can do something.
Examples include:
- look up an order,
- change an address,
- cancel a subscription,
- issue a credit,
- schedule a replacement,
- create a case,
- update CRM fields,
- trigger identity verification.
At this point, model quality is only one control.
A production tool layer should also include:
- strict function schemas — do not let free-form model text become an account action;
- server-side authorization — the model must never define its own permissions;
- policy checks — validate refund limits, eligibility and account state deterministically;
- idempotency — retries must not create duplicate refunds or orders;
- human approval for high-impact actions;
- audit logs that capture the request, tool call, result and final response.
Gemini 2.5 Flash-Lite supports function calling, and the GPT-5.6 and Claude families support tool-oriented agent workflows. Mistral Small 4 also documents function calling and agent/conversation APIs.
But a tool checkmark does not tell you whether a model will reliably choose the correct tool and parameters under your policy.
That needs task-level testing.
Stage 4: Escalate hard cases
The strongest routing system knows when not to keep answering with the cheap tier.
Escalation candidates include:
- repeated failed attempts,
- contradictory policy,
- emotionally sensitive complaints,
- regulated or legal issues,
- high-value customers,
- account-security concerns,
- unusual tool failures,
- low confidence,
- cases requiring negotiation or judgment.
Anthropic explicitly positions Claude Sonnet 5 for customer-facing agents and high-volume production use, while also giving it higher-end reasoning and tool-use capability than a lightweight classifier.
At current standard pricing, Sonnet 5 is $2 input / $10 output per million tokens.
That is considerably more expensive than Luna or Flash-Lite on raw token price, but an escalation layer handles only a fraction of traffic if routing works properly.
The economic question is therefore not:
Is Sonnet cheaper than Flash-Lite?
It is:
Does using a stronger model on the difficult 5–15% of cases increase resolution enough to reduce human work or repeat contacts?
Only your production evaluation can answer that.
Where Mistral Small 4 fits
Mistral Small 4 is interesting for a different reason.
Mistral describes it as a multimodal, multilingual hybrid model for general chat, reasoning and agentic workloads. Current hosted API pricing is $0.15 input / $0.60 output per million tokens, and the model is released under Apache 2.0 with published weights.
That creates an additional architecture path:
- start with the hosted API,
- fine-tune or specialize if needed,
- retain the option to deploy the weights in a controlled environment.
For organizations with strict data-location requirements or a strategic preference for open-weight infrastructure, this can matter more than a small benchmark difference.
Self-hosting is not automatically cheaper. Hardware, inference optimization, redundancy and operations must be included in TCO.
A practical routing shortlist
This table is a starting architecture, not a performance ranking.
| Support layer | Models worth evaluating | Selection signal |
|---|---|---|
| Intent / classification / extraction | Gemini 2.5 Flash-Lite, GPT-5.6 Luna, Mistral Small 4 | Low latency, low cost, structured accuracy |
| Routine grounded answers | Luna, Flash-Lite, Small 4 | Policy fidelity, retrieval quality, multilingual fit |
| Long customer history / large docs | Luna, Flash-Lite | ~1M context headroom |
| Complex customer-facing agent | Claude Sonnet 5 | Higher capability tier with provider positioning for customer-facing agents |
| Controlled/self-hosted support stack | Mistral Small 4 | Apache 2.0 weights + hosted API option |
| High-risk case | Strong model + human | Resolution quality and safety outweigh token cost |
The correct model may be different by language, product line or support channel.
Build an evaluation set from real tickets
Do not start by benchmarking generic prompts.
Take a representative sample of historical support cases and label the expected behavior.
Include:
- easy FAQs,
- ambiguous requests,
- angry customers,
- misspellings and slang,
- multiple languages,
- missing order numbers,
- contradictory knowledge-base articles,
- refund requests near policy limits,
- tool failures,
- security-sensitive account changes,
- long conversation histories,
- cases that should escalate.
For each case, define what success means before running the model.
Metrics that matter more than "helpfulness"
A support model can sound excellent and still be operationally poor.
Track at least:
Triage accuracy
Did the system route the case to the correct intent and queue?
Grounding / policy accuracy
Did the answer follow the current approved policy?
First-contact resolution
Was the customer's issue actually resolved without another contact?
Containment
What percentage of eligible cases were resolved without a human?
Containment should never be maximized blindly. A system that refuses to escalate can produce a high containment number and terrible customer outcomes.
Escalation precision
Did the AI escalate the cases that genuinely needed a human without sending easy work unnecessarily?
Tool success
Did the correct tool run with the correct parameters and expected side effect?
Latency
A customer-facing workflow has different latency requirements from a nightly back-office job.
Cost per resolved case
This is the key economic metric.
Include:
- model tokens,
- retrieval,
- tool calls,
- retries,
- premium-model escalations,
- human minutes,
- repeat contacts.
A cheap model that causes more retries or human cleanup may be the expensive architecture.
Example routing policy
A simple production design might look like this:
Step 1 — Lightweight triage
Run a low-cost model to classify the ticket and extract structured fields.
Step 2 — Retrieve evidence
Fetch only the relevant policy, product data and customer context.
Step 3 — Generate or act
For low-risk informational questions, generate the answer.
For account actions, ask the model for a structured tool call and validate it server-side.
Step 4 — Confidence and policy gate
Escalate if:
- evidence is missing,
- policies conflict,
- the action exceeds a limit,
- tool execution fails,
- the ticket matches a high-risk category,
- model confidence or an external verifier falls below the threshold.
Step 5 — Premium model or human
A stronger model can attempt complex reasoning or summarize the case for a human agent.
This architecture lets premium inference focus on cases where it can create economic value.
Multilingual support needs its own test set
Provider labels such as "multilingual" are useful for discovery but insufficient for deployment.
A customer-support system should evaluate each important language separately.
Check:
- intent accuracy,
- policy comprehension,
- tone,
- local product names,
- address and date formats,
- transliterated input,
- code-switching,
- regional legal language.
Do not assume English evaluation results transfer directly to Croatian, German, Spanish, Japanese or any other support market.
Security and privacy are routing requirements
Customer-support prompts can contain:
- names,
- addresses,
- account IDs,
- order history,
- payment-related information,
- health or other sensitive context.
Model selection therefore depends on the exact provider contract and deployment path, not only the model name.
Before production, document:
- what data is sent,
- where it is processed,
- retention policy,
- training/data-use policy,
- access controls,
- regional processing requirements,
- auditability,
- deletion flow.
For open-weight/self-hosted deployments, provider data handling may be reduced, but responsibility for securing the inference environment moves to your organization.
Pair this guide with the cost model
This article answers how to route support work.
For volume economics, use our separate analysis:
AI Customer Support Cost: 1,000 to 100,000 Conversations
For token-level scenario modeling, use the AI World Scope Pricing Calculator.
And for the mechanics that change the real bill — caching, Batch/Flex and long-context pricing — see AI API Pricing Explained: Cache, Batch, Long Context & Effective Cost.
AI World Scope take
The best customer-support architecture is usually not one model.
Use the cheapest reliable model for deterministic, high-volume work. Ground normal answers in current evidence. Put hard permission boundaries around tools. Escalate the minority of difficult cases to stronger inference or a human.
Then evaluate the system using resolution, policy accuracy and total cost, not just answer quality.
Route by task. Escalate by risk. Optimize cost per resolved customer problem.
Sources & Documentation
Sources used for this article, with source type and publisher shown where available.
- documentationGemini 2.5 Flash-Lite model documentationVisit Source
- documentationGPT-5.6 Luna model documentationVisit Source
- officialClaude Sonnet 5 announcementVisit Source
- officialClaude Sonnet model pageVisit Source
- officialMistral Small 4 announcementVisit Source
- documentationMistral Small 4 model documentationVisit Source